Research · October 2026 edition
AI-Search Readiness of Top Sites What the top 9,973 sites say about themselves, and whether a crawler that runs no scripts can read it.
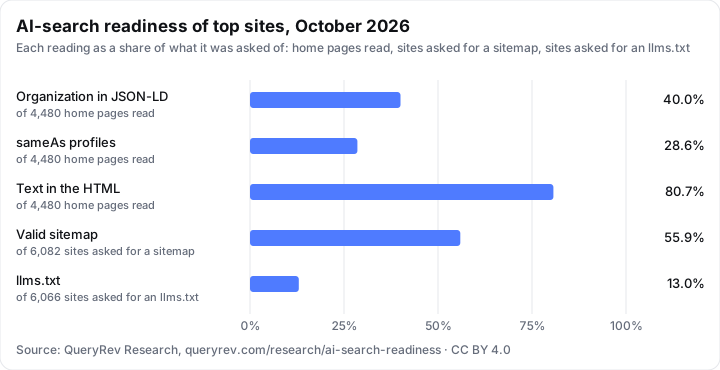
40.0% of the home pages read describe the organization in structured data, and 80.7% carry their main text in the HTML as served. 55.9% of the sites asked have a valid sitemap, and 13.0% of the sites asked have an llms.txt.
Sites asked are the sites read, less those whose robots.txt keeps our crawler from the file, so “of sites asked” and “of sites read” differ.
- Measured
- 24 October 2026
- Panel
- 9,973 domains, Tranco list N26XW
- Updated
- A full reading each quarter
- Author
- QueryRev Research
Crawlers covered
What each one doesThis study reads files as one crawler, QueryRevBot. “Open to AI search” uses the crawlers of the crawler study.
The 11 AI crawlers of the crawler study, from OpenAI, Perplexity, Google, Apple, Common Crawl, Meta, Amazon and ByteDance. Other crawlers are not checked.
Key figures
Five readings, each on what it was asked of.
A reading is a count of files read by fixed rules, shown as a share of what it was asked of: the home pages read, the sites asked for a sitemap, the sites asked for an llms.txt. Every tile names its denominator and the count.
What a share is of
- The share shown largeThe home pages read (4,480), or for a sitemap and an llms.txt the sites that were asked for the file.
- A narrower shareAmong a smaller group: the pages with structured data (2,203) or the pages that describe an Organization (1,793).
- A wider shareAmong a larger group, such as the sites read (6,342), where the figure was asked of fewer.
Organization in JSON-LD
of 4,480 home pages read
40.0%
sameAs profiles
of 4,480 home pages read
28.6%
Text in the HTML
of 4,480 home pages read
80.7%
Valid sitemap
of 6,082 sites asked for a sitemap
55.9%
llms.txt
of 6,066 sites asked for an llms.txt
13.0%
Each bar is a share of its own denominator, named under its label: the home pages read for the first three, the sites asked for a sitemap, the sites asked for an llms.txt.
Show the numbers as a table
| Reading | Counted | Share |
|---|---|---|
| Organization in JSON-LD | 1,793 | 40.0% |
| sameAs profiles | 1,280 | 28.6% |
| Text in the HTML | 3,615 | 80.7% |
| Valid sitemap | 3,401 | 55.9% |
| llms.txt | 787 | 13.0% |
Panel
4,480 of 9,973 home pages could be read.
The panel is the crawler study’s: the first 10,000 places of Tranco list N26XW, created 14 October 2026. 2 places were not a valid domain and 25 domains of companies that build language models were left out. Our crawler asks for robots.txt first and for the home page only if robots.txt allows it.
0
Sites that opted out
A QueryRevBot group in robots.txt closes the whole site to our crawler. Nothing else is asked, and the site is left out of the per-domain data.
Domains not read, by cause
First the robots.txt answer, then the home page. Shares are of the whole panel. A domain is counted once, under the first thing that stopped it.
Stopped at robots.txt
| The name did not resolve | 1,389 | 13.9% |
|---|---|---|
| No answer within 10 seconds | 302 | 3.0% |
| Connection or TLS failed | 254 | 2.5% |
| Resolved to a private or reserved address | 52 | 0.5% |
| Refused our crawler (401 or 403) | 1,052 | 10.5% |
| Asked us to slow down (429) | 20 | 0.2% |
| Server error (5xx) | 60 | 0.6% |
| Redirects that could not be followed | 25 | 0.3% |
| Another answer | 1 | <0.1% |
| A bot check or a web page, not the file | 476 | 4.8% |
| Opted out of the study | 0 | 0.0% |
The home page could not be used
| robots.txt keeps our crawler from the home page | 242 | 2.4% |
|---|---|---|
| The robots.txt of the page it landed on could not be read | 16 | 0.2% |
| Over 2 MiB and cut with too little text to measure | 13 | 0.1% |
| Refused our crawler (401 or 403) | 596 | 6.0% |
| A bot check | 30 | 0.3% |
| A parking page or a default server page | 3 | <0.1% |
| Not an HTML page | 26 | 0.3% |
| An error answer | 263 | 2.6% |
| Redirected to another domain, which is not followed | 633 | 6.3% |
| Redirects that could not be followed | 12 | 0.1% |
| No answer, or the connection failed | 28 | 0.3% |
Structured data
49.2% of home pages read carry schema.org JSON-LD.
JSON-LD is read as served. A page whose structured data is added by a script, a tag manager for instance, is not in the HTML a crawler without scripts receives, and counts as having none.
Organization
34.5%
WebSite
34.5%
ImageObject
24.5%
SearchAction
23.0%
WebPage
18.4%
ListItem
13.3%
PostalAddress
13.2%
ContactPoint
12.0%
EntryPoint
11.2%
BreadcrumbList
11.1%
Person
6.2%
PropertyValueSpecification
5.8%
NewsMediaOrganization
5.6%
SiteNavigationElement
5.3%
ReadAction
5.0%
ItemList
4.0%
CollectionPage
3.7%
Answer
3.7%
Question
3.7%
FAQPage
3.6%
Each type counted once per home page, as a share of the home pages read. 171 types were seen in all; the most common are shown.
Show the numbers as a table
| Type | Home pages | Share |
|---|---|---|
| Organization | 1,545 | 34.5% |
| WebSite | 1,544 | 34.5% |
| ImageObject | 1,096 | 24.5% |
| SearchAction | 1,031 | 23.0% |
| WebPage | 823 | 18.4% |
| ListItem | 598 | 13.3% |
| PostalAddress | 592 | 13.2% |
| ContactPoint | 539 | 12.0% |
| EntryPoint | 502 | 11.2% |
| BreadcrumbList | 496 | 11.1% |
| Person | 278 | 6.2% |
| PropertyValueSpecification | 259 | 5.8% |
| NewsMediaOrganization | 250 | 5.6% |
| SiteNavigationElement | 239 | 5.3% |
| ReadAction | 222 | 5.0% |
| ItemList | 181 | 4.0% |
| CollectionPage | 166 | 3.7% |
| Answer | 165 | 3.7% |
| Question | 165 | 3.7% |
| FAQPage | 163 | 3.6% |
Organization
What an Organization says about itself.
Of the pages that describe an Organization (1,793), how many give a name and a web address, a logo and the profiles it is on. The Organization is the first node whose address is on the site’s own domain, else the first.
Wikidata
10.7%
Wikipedia
26.4%
LinkedIn
58.3%
X
82.7%
Facebook
81.5%
Instagram
62.3%
YouTube
65.8%
TikTok
18.4%
GitHub
6.8%
Crunchbase
4.0%
Pinterest
8.4%
Another host
33.0%
Each kind counted once per site, by the host of the address, as a share of the Organizations with sameAs (1,280).
Show the numbers as a table
| The kinds of profile sameAs points to | Sites | Share |
|---|---|---|
| Wikidata | 137 | 10.7% |
| Wikipedia | 338 | 26.4% |
| 746 | 58.3% | |
| X | 1,058 | 82.7% |
| 1,043 | 81.5% | |
| 797 | 62.3% | |
| YouTube | 842 | 65.8% |
| TikTok | 236 | 18.4% |
| GitHub | 87 | 6.8% |
| Crunchbase | 51 | 4.0% |
| 108 | 8.4% | |
| Another host | 422 | 33.0% |
Text in the HTML
80.7% of home pages read carry their main text in the HTML as served.
This is what a crawler that runs no scripts receives. The study does not say what a page shows after its scripts run.
Home pages over 2 MiB, read as far as the cut and flagged: 49 of 4,480.
Sitemaps and llms.txt
55.9% of the sites asked have a valid sitemap, and 13.0% an llms.txt.
One sitemap file is read per site, and the children of an index are not. An llms.txt is counted by the crawler study’s rule, read again on this panel, so both studies can be set side by side.
A valid sitemap
55.9%
No sitemap found
22.0%
A web page, not a sitemap
4.2%
A file that is not a valid sitemap
4.1%
The request failed
13.8%
Shares of the 6,082 sites asked for a sitemap: the 6,342 sites read, less 260 whose robots.txt keeps our crawler from the sitemap. Those 260 sites are not in the bars.
Show the numbers as a table
| What the sitemap request found | Sites | Share |
|---|---|---|
| A valid sitemap | 3,401 | 55.9% |
| No sitemap found | 1,336 | 22.0% |
| A web page, not a sitemap | 256 | 4.2% |
| A file that is not a valid sitemap | 250 | 4.1% |
| The request failed | 839 | 13.8% |
Valid sitemaps cut at 5 MiB and counted as valid as far as read: 39 of 3,651 sitemaps found. Sites whose robots.txt keeps our crawler from /llms.txt were not asked for one (276). The trend of llms.txt over time is in the crawler study.
By rank
The same readings, by rank band.
The panel in two bands of the list. Each reading keeps its own denominator, named in the column heading.
| Group | Home pages read | Organization in JSON-LD | sameAs | Text in the HTML | Valid sitemap | llms.txt | All five |
|---|---|---|---|---|---|---|---|
| Places 1 to 1,000 | 362 | 40.9%148 of 362 home pages read | 31.2%113 of 362 home pages read | 76.5%277 of 362 home pages read | 55.4%298 of 538 sites asked for a sitemap | 17.2%92 of 536 sites asked for an llms.txt | 14.4%52 of 362 home pages read |
| Places 1,001 to 10,000 | 4,118 | 39.9%1,645 of 4,118 home pages read | 28.3%1,167 of 4,118 home pages read | 81.1%3,338 of 4,118 home pages read | 56.0%3,103 of 5,544 sites asked for a sitemap | 12.6%695 of 5,530 sites asked for an llms.txt | 7.2%298 of 4,118 home pages read |
Column shares: Organization, sameAs, text and all five of home pages read; sitemap of sites asked for a sitemap; llms.txt of sites asked for an llms.txt.
By country-code domain
The same readings, by country-code ending.
Endings with at least 50 domains in the panel. The readings and their denominators are those of the rank bands above.
| Group | Home pages read | Organization in JSON-LD | sameAs | Text in the HTML | Valid sitemap | llms.txt | All five |
|---|---|---|---|---|---|---|---|
| .ru | 146 | 30.8%45 of 146 home pages read | 24.7%36 of 146 home pages read | 81.5%119 of 146 home pages read | 61.3%114 of 186 sites asked for a sitemap | 10.9%20 of 184 sites asked for an llms.txt | 7.5%11 of 146 home pages read |
| .jp | 98 | 25.5%25 of 98 home pages read | –Not shown | 85.7%84 of 98 home pages read | 55.0%66 of 120 sites asked for a sitemap | 5.8%7 of 120 sites asked for an llms.txt | 2.0%2 of 98 home pages read |
| .io | 75 | 44.0%33 of 75 home pages read | 32.0%24 of 75 home pages read | 89.3%67 of 75 home pages read | 56.0%61 of 109 sites asked for a sitemap | 25.0%27 of 108 sites asked for an llms.txt | 21.3%16 of 75 home pages read |
| .de | 109 | 43.1%47 of 109 home pages read | 27.5%30 of 109 home pages read | 93.6%102 of 109 home pages read | 64.2%86 of 134 sites asked for a sitemap | 9.7%13 of 134 sites asked for an llms.txt | 5.5%6 of 109 home pages read |
| .uk | 41 | –Not shown | –Not shown | 92.7%38 of 41 home pages read | 63.5%33 of 52 sites asked for a sitemap | 5.8%3 of 52 sites asked for an llms.txt | 2.4%1 of 41 home pages read |
| .br | 51 | 52.9%27 of 51 home pages read | –Not shown | 74.5%38 of 51 home pages read | 57.6%38 of 66 sites asked for a sitemap | 21.2%14 of 66 sites asked for an llms.txt | 9.8%5 of 51 home pages read |
| .in | 46 | –Not shown | –Not shown | 67.4%31 of 46 home pages read | 47.4%27 of 57 sites asked for a sitemap | 12.3%7 of 57 sites asked for an llms.txt | 2.2%1 of 46 home pages read |
| .cn | 43 | –Not shown | –Not shown | 67.4%29 of 43 home pages read | 28.3%15 of 53 sites asked for a sitemap | 1.9%1 of 53 sites asked for an llms.txt | 2.3%1 of 43 home pages read |
| .fr | 49 | 53.1%26 of 49 home pages read | –Not shown | 85.7%42 of 49 home pages read | 62.2%46 of 74 sites asked for a sitemap | 4.1%3 of 74 sites asked for an llms.txt | 0.0%0 of 49 home pages read |
| .it | 43 | –Not shown | –Not shown | 83.7%36 of 43 home pages read | 60.7%34 of 56 sites asked for a sitemap | 5.5%3 of 55 sites asked for an llms.txt | 4.7%2 of 43 home pages read |
| .tv | 37 | –Not shown | –Not shown | 78.4%29 of 37 home pages read | 63.5%33 of 52 sites asked for a sitemap | 0.0%0 of 52 sites asked for an llms.txt | 0.0%0 of 37 home pages read |
| .co | 24 | –Not shown | –Not shown | –Not shown | 43.2%16 of 37 sites asked for a sitemap | 0.0%0 of 37 sites asked for an llms.txt | –Not shown |
| .es | 37 | –Not shown | –Not shown | 78.4%29 of 37 home pages read | 46.8%22 of 47 sites asked for a sitemap | 6.4%3 of 47 sites asked for an llms.txt | 2.7%1 of 37 home pages read |
| .pl | 35 | –Not shown | –Not shown | 80.0%28 of 35 home pages read | 43.5%20 of 46 sites asked for a sitemap | 10.6%5 of 47 sites asked for an llms.txt | 2.9%1 of 35 home pages read |
Rows under 30 sites are not shown: a share is left out of a table when any denominator it is shown on holds fewer than 30 sites. The count of home pages read is always shown.
Method
How we measured, and what it cannot tell you.
One run with our own crawler, and one more try for the sites that failed on the network. Every figure is a count of files read by fixed rules: no model makes a figure or a label, and there is no score.
The panel
The first 10,000 places of Tranco list N26XW, less the domains of companies that build language models: 9,973 domains.
Details
It is the panel of the crawler study. Tranco ranks registrable domains, combined from several sources over 30 days; list N26XW was created 14 October 2026. 2 places were not a valid domain and were left out, and 25 domains of companies that build language models are not requested at all. The list includes domains that serve no website, such as networks and APIs; they are counted as not read.
What was fetched
robots.txt, the home page, /llms.txt and one sitemap, each only if robots.txt allows it. Nothing else.
Details
For each domain, in this order and one after the other: https://domain/robots.txt (the www. host instead when the domain did not connect); the home page; the robots.txt of the host the home page landed on when that is another host; /llms.txt; and the sitemap, which is the first Sitemap line of robots.txt on the same registrable domain, else /sitemap.xml. No inner page, no script run, no cookie, and no link of an llms.txt is followed. A redirect to another registrable domain is not followed. Requests identified themselves as QueryRevBot, with a page that says how to stop it; at most 16 domains were in flight, requests to one host were at least a second apart, a Crawl-delay was kept up to 10 seconds, and nothing more was asked of a host after a 429 or 503. A domain that failed for network reasons was tried once more at the end.
What counts as read
6,342 of the 9,973 domains gave a robots.txt answer we could read; 4,480 of them gave a home page we could use.
Details
A home page is read when it answers 200 within the redirects with an HTML body that is not a bot check (a 202, or a page with a challenge’s marks) or a placeholder (a parking page or a default server page, by a fixed list of marks). A body over 2 MiB is read as far as the cut and flagged; when the part read holds under 150 words of main text, the page is not counted as read at all, because the cut may have hidden its text and its structured data. A page is decoded by its own character set. Sites that opted out of the study (0) count only as opted out. The causes of every domain not read are listed under Panel.
How structured data was read
JSON-LD blocks that parse and name schema.org, walked to any depth; microdata types; RDFa is not read.
Details
A block of type application/ld+json counts when it parses as JSON, after a wrapping comment or CDATA is removed, with a top-level @context that names schema.org. The reader is bounded: at most 50 blocks, 512 KiB each and 1 MiB in all, depth 16 and 5,000 nodes; past a bound the rest is not read and the page is flagged. An Organization is any node whose @type is Organization or one of its schema.org subtypes, taken from the schema.org vocabulary at release 30.1. Only type names of that vocabulary are published; any other name is published as other. Organization names and sameAs addresses are read but never published: only counts and the kind of profile are.
How text was counted
Words of main text in the HTML as served, at least 150 for text in the HTML.
Details
Main text is the text of main (or an element with role main) when there is one, else of the body without header, nav, footer and aside. Script, style, noscript, template and svg are never counted. Words are counted with Intl.Segmenter, so pages in Chinese or Japanese are counted too. A page of over 5 KiB with under 50 words and an application root element or a notice to enable JavaScript is an empty app shell; the rest under 150 words is little text.
Sitemaps and llms.txt
A sitemap is valid when it is XML or text with addresses on the site’s domain; an llms.txt by the crawler study’s rule.
Details
A sitemap is valid when the file answered 2xx and is XML without a DOCTYPE or ENTITY whose root is urlset or sitemapindex with at least one loc that is an absolute web address on the site’s registrable domain, or a text sitemap of such addresses. A web page served at /sitemap.xml is not a sitemap. A file cut at 5 MiB counts as valid as far as read. An llms.txt counts when /llms.txt answers 200 with a text type, the body is not an HTML page or a robots.txt, and its first non-empty line is a Markdown title.
The network-failure retry
1,004 sites whose first try ended in a network failure were asked again from the start, from a connection in the United States, on 24 October 2026.
Details
A network can fail to reach a site that answers from another. Every site whose result stood on a network failure (no answer, a timeout, a failed connection, an address refused as private or reserved, or a home page, sitemap or llms.txt that did not answer) was asked again from the start, as above, from a connection in the United States, on 24 October 2026, with the same limits and politeness. For each, the better of the two tries is kept: 294 of the 1,004 read more the second time. A name that did not resolve, a refusal (401 or 403), a bot check, a 429 and a 5xx were not a reason to ask again, because they are what the site answered.
What each figure counts
Every figure, its rule and the denominators it is shown on. Each name leads to the figure on this page.
- Home pages read
Shown on: Whole panel, Sites read
The home page answered 200 within the redirects with an HTML body that is not a bot check or a placeholder.
- Any JSON-LD
Shown on: Home pages read
A script of type application/ld+json that parses as JSON with a top-level @context naming schema.org.
- A block that does not parse
Shown on: Pages with a JSON-LD script
At least one such script that fails to parse.
- Organization in JSON-LD
Shown on: Home pages read, Pages with schema.org JSON-LD
A node, at any depth (@graph, arrays, nested values), whose @type is Organization or one of its schema.org subtypes (vocabulary release 30.1).
- Organization only in microdata
Shown on: Home pages read
An itemtype naming one of those types, and none in JSON-LD.
- Name and web address
Shown on: Home pages read, Pages describing an Organization
The primary Organization (the first whose address is on the site’s registrable domain, else the first) has a non-empty name and an absolute http or https address.
- Logo
Shown on: Pages describing an Organization
The primary Organization has a logo: an address, or an image with an address.
- sameAs
Shown on: Home pages read, Pages describing an Organization
The primary Organization’s sameAs holds at least one absolute http or https address outside the site’s own registrable domain.
- Profiles linked
Shown on: Organizations with sameAs
Per kind of host: Wikidata, Wikipedia, LinkedIn, X, Facebook, Instagram, YouTube, TikTok, GitHub, Crunchbase, Pinterest, another host. A site counts once per kind.
- Profiles per site
Shown on: Organizations with sameAs
The median and quartiles, nearest rank, of the number of distinct sameAs addresses.
- WebSite, and its SearchAction
Shown on: Home pages read
A WebSite node; and one whose potentialAction is a SearchAction.
- FAQ
Shown on: Home pages read, Pages with schema.org JSON-LD
A FAQPage node, in JSON-LD or microdata.
- Types in use
Shown on: Home pages read, Pages with schema.org JSON-LD
The 20 schema.org types found on the most home pages, each counted once per page.
- Text without scripts
Shown on: Home pages read
At least 150 words of main text in the HTML as served.
- Served as an empty app shell
Shown on: Home pages read
Over 5 KiB of HTML, under 50 words of main text, and an application root element or a notice to enable JavaScript.
- Little text, no shell marks
Shown on: Home pages read
Under 150 words of main text, without the shell marks.
- Home page says noindex
Shown on: Home pages read
A robots meta tag or an X-Robots-Tag header, without an agent prefix, with noindex.
- robots.txt lists a sitemap
Shown on: Sites read, Sites with a robots.txt file
At least one Sitemap line.
- A valid sitemap
Shown on: Sites asked for a sitemap
The file of the sitemap request is a sitemap by the rule under Sitemaps and llms.txt.
- A sitemap index
Shown on: Sitemaps found
The valid file is a sitemapindex.
- llms.txt
Shown on: Sites read, Sites asked for an llms.txt
The crawler study’s rule: 200, a text type, not HTML, not a robots.txt, and a Markdown title first.
- Text in the HTML, and open to AI search crawlers
Shown on: Home pages read
Text in the HTML, and robots.txt lets every covered crawler whose purpose is search or user fetch read the home page.
- All five readings
Shown on: Home pages read
Organization in JSON-LD with sameAs, text in the HTML, a valid sitemap and an llms.txt. A count, not a score.
- Not read, by cause
Shown on: Whole panel
Each domain of the panel that was not read, under the first thing that stopped it.
Limits
- One page per site, the home page, as served to our crawler when it was read. An Organization described on an inner page, often /about, is not seen.
- Structured data added by scripts is not in the HTML as served and is counted as absent.
- Valid means the rules above, not a search engine’s rich-result eligibility or a full schema.org validation.
- A site that refuses our crawler or serves a bot check is not read; it may treat other crawlers differently.
- One sitemap file is read; the pages it lists and the children of an index are not checked.
- Main text includes what a page puts inside main. A page without main is counted without its header, navigation and footer, and some boilerplate may remain.
- The panel includes domains that serve no website (networks, APIs, CDNs); they are counted as not read.
- A home page that went over 2 MiB and was cut, with under 150 words of main text in the part read, is counted apart and is in no home-page figure: the cut may have hidden its text and its structured data. A page cut with 150 words or more stays in, and is flagged.
- A row of a rank band or a country-code ending is published only when every denominator its shares are shown on holds at least 30 sites; the quartiles of profiles per site go with it.
- 1,004 sites were asked twice, the second time from a connection in the United States; the figures keep the better of the two tries for each, so some are counted on what a site served to that connection. A site can serve a different page to a different network or at a different time.
Other studies, and how this one differs
- The Web Almanac: Structured data (2024): the yearly chapter by the HTTP Archive on how pages use JSON-LD, Microdata and RDFa, and sameAs.
- Web Data Commons: structured data: structured data extracted from the Common Crawl, with statistics on how the formats are used.
This study reads one fixed panel again every quarter; reads the organization, the sitemap, the llms.txt and the text of the same home page together; counts text in the HTML as served rather than after scripts; and gives every figure on the denominators it is shown on. Their figures are not quoted here; follow the links for them.
Data
Download, cite or embed it.
The data is free to use under CC BY 4.0: copy, share and adapt it, with a credit and a link to this page.
- Per-domain results (CSV)One row per domain of the panel, sites that opted out left out: what we read, and the kinds of structured data found. Organization names and sameAs addresses are not in it.
- Every figure (CSV)Each figure with its count, its denominators and shares, overall, by rank band and by country-code ending.
- Every count (JSON)The counts this page is built from, as one JSON file.
- Schema.org types seen (CSV)Every schema.org type found on a home page, and the number of home pages it is on.
Cite this study
QueryRev Research (2026). AI-search readiness of top sites, October 2026 edition. https://queryrev.com/research/ai-search-readiness. CC BY 4.0
BibTeX
@misc{queryrev2026readiness10,
  author = {QueryRev Research},
  title = {AI-search readiness of top sites, October 2026 edition},
  year = {2026},
  month = oct,
  publisher = {QueryRev AI},
  url = {https://queryrev.com/research/ai-search-readiness},
  note = {CC BY 4.0}
}The panel comes from Tranco
Le Pochat et al., “Tranco: A Research-Oriented Top Sites Ranking Hardened Against Manipulation,” NDSS 2019. List N26XW: https://tranco-list.eu/list/N26XW
Embed this chart
An image of the five readings, with a link back. No script: paste it where your page takes HTML.
<a href="https://queryrev.com/research/ai-search-readiness#key-figures"><img src="https://queryrev.com/data/ai-search-readiness/2026-10/readings.svg" width="720" alt="The five readings of the top sites’ home pages and public files, each as a share of what it was asked of: Organization in JSON-LD, sameAs, text in the HTML, valid sitemap and llms.txt, October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness">AI-Search Readiness of Top Sites, QueryRev Research</a> (CC BY 4.0)</p>
Questions
Is this a readiness score?
No. The study gives counts of files read by fixed rules, each with the denominators it is shown on. “All five readings” is a count of home pages that have all five, not a grade, and no site is ranked.
Why is the text counted from the HTML as served?
A crawler that does not run scripts receives the HTML as served, and this study reports what such a crawler receives. It does not say what a page shows after its scripts run.
Does structured data added by a tag manager count?
No. It is not in the HTML as served, so it is counted as absent. That is a limit of reading files without running scripts, and it is listed under Limits.
Which crawlers does “open to AI search” cover?
The AI crawlers of the crawler study, whose list is on that page. The study reads files as one crawler, QueryRevBot; it does not say how any other crawler treats a site.
How do I keep my site out of this study?
Add User-agent: QueryRevBot with Disallow: / to your robots.txt. We still read robots.txt itself, as every crawler must, but nothing else, and your site is left out of the per-domain data and counted only as opted out.
Keep exploring