Skip to content
Join the waitlist

QueryRev Research

Research Original data on how the web meets AI search.

QueryRev Research measures the web with our own crawler and publishes what it finds. Every figure is computed from the files read, the method is on the page, and the data is free to reuse under CC BY 4.0.

Studies
1
Domains in the panel
9,973
Licence
CC BY 4.0
Author
QueryRev Research

Updated

Studies

Each study is one page, measured again on a schedule. A new reading updates the page, adds a line to its change log and publishes dated data files.

October 2026 editionMeasured 15 October 2026

State of AI Crawler Access

What the top 9,973 sites tell 11 AI crawlers from 8 vendors in robots.txt, and whether their llms.txt holds up.

Blocked by name, by what the crawler is for

  • AI training7.9%
  • AI search4.8%
  • User fetch3.6%

Average share of the 6,294 sites read, over the crawlers of each purpose.
Cadence

The panel stays fixed, so a change between two readings is a change on the web, not in the list. Each study keeps one page; a new reading never makes a thin new one.

  1. Monthly

    A monthly pulse

    robots.txt and llms.txt read again on the same panel. What changed goes into the change log, with dated data files.

  2. On news

    Within 48 hours of crawler news

    A re-run when a crawler or a common robots.txt template changes, added to the same change log.

  3. Quarterly

    A full report each quarter

    Every figure again, by crawler, rank band and country-code ending.

  4. Yearly

    An annual edition

    Once a year, the study as a full edition of “State of AI crawler access”.

Change log

Every reading of every study, newest first.

  1. State of AI Crawler Access · October 2026

    First edition: 9,973 domains of Tranco list N26XW read. This reading is the baseline the next ones are compared with.

    Read this reading

Open data

Every file is free to use under CC BY 4.0: copy it, share it and adapt it, with a credit and a link to the study.

  • ShareCopy and redistribute the files in any medium.
  • AdaptCut, combine and build on them, for any purpose.
  • CreditName QueryRev Research, link to the study and say what you changed.

The licence: CC BY 4.0

Method and licence

Each study page carries its full method and its limits. These rules hold for all of them.

  • Read by our own crawler

    QueryRevBot identifies itself and links to its page. A site that keeps it out by name is left out of the per-domain data and counted only as opted out.

  • Counted from the files

    robots.txt is parsed as RFC 9309 sets it out, llms.txt is checked against llmstxt.org. Every figure is a count over those files; no model makes a figure or a label.

  • Every share names what it is of

    Studies disagree mostly because they divide by different things. Each share is given with its denominator, and the study gives each headline figure on three.

  • Limits stated

    robots.txt is a request, not enforcement; a CDN or firewall rule is not visible; domains that did not answer are counted apart.

Studies are written and published by QueryRev Research, the research team of QueryRev AI, under the organisation’s name.

Read the full method

Press desk

Use any figure with a credit and a link. Each figure has its own anchor on the study page, and an anchor never changes once published.

How to cite

The citation names the study, the day it was measured, the page and the dataset’s DOI.

QueryRev Research. “State of AI crawler access, October 2026 (dataset).” QueryRev AI, 15 October 2026. https://queryrev.com/research/ai-crawler-access. Dataset: https://doi.org/10.5281/zenodo.23424275

Embed the chart

An image of the chart by crawler, linked back to it. No script.

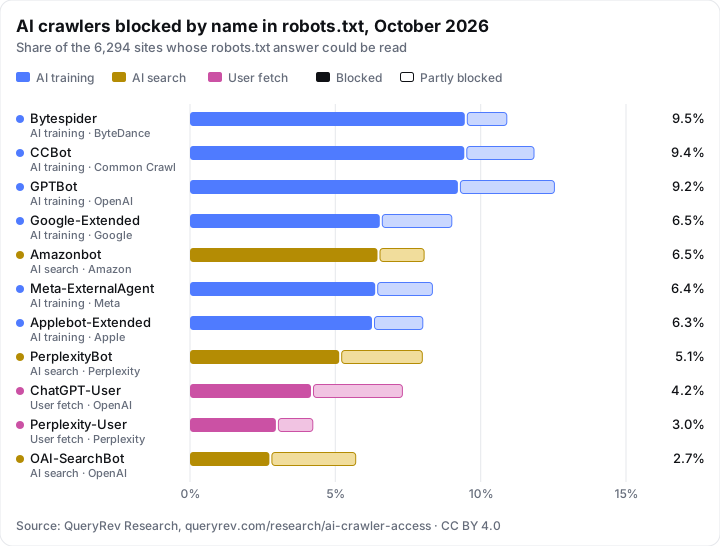
Share of top sites that block each AI crawler by name in robots.txt, October 2026. Source: QueryRev Research.
<a href="https://queryrev.com/research/ai-crawler-access#by-agent"><img src="https://queryrev.com/data/ai-crawler-access/2026-10/block-rates.svg" width="720" alt="Share of top sites that block each AI crawler by name in robots.txt, October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-crawler-access">State of AI Crawler Access, QueryRev Research</a> (CC BY 4.0)</p>

Questions

Can I use the data in my own article or research?

Yes. The data is published under CC BY 4.0: you may copy, share and adapt it for any purpose, with a credit to QueryRev Research and a link to the study.

How should I cite a study?

Copy the citation from the press desk on this page or the Data section of the study. It names the study, the day it was measured, the page and the dataset’s DOI.

How often are the figures updated?

Each study is read again every month on the same panel, re-run within 48 hours of major crawler news, and reported in full each quarter. Every reading goes into the study’s change log with dated data files.

Who writes the studies?

QueryRev Research, the research team of QueryRev AI. Studies are published under the organisation’s name, and every figure is computed from the files our own crawler reads.

Keep exploring