Research · Tracker
AI-Search Readiness Tracker Every reading of the same panel, figure by figure.
How the top sites describe themselves to AI search: structured data, a sitemap, an llms.txt and text in the HTML, read again on the same panel. Each figure is a count over the pages or sites asked, with the day it was read.
- Readings
- 1
- Latest reading
- 24 October 2026
- Panel
- 9,973 domains, Tranco list N26XW
- Licence
- CC BY 4.0
Updated
Figures
Each figure, reading by reading.
A figure is a count over the sites or pages read in one reading. The scale starts at zero, and every reading names the number it is a share of.
This tracker holds 1 reading. A figure draws a line once it has a second reading.
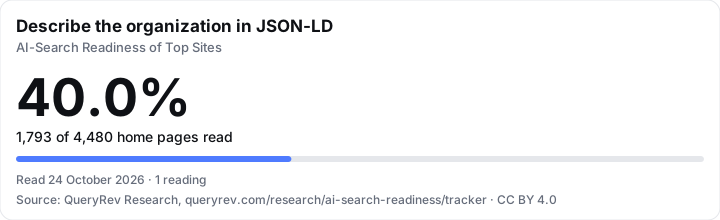
Describe the organization in JSON-LD 40.0%
1,793 of 4,480 home pages read
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
<a href="https://queryrev.com/research/ai-search-readiness/tracker#organization-schema"><img src="https://queryrev.com/data/tracker/ai-search-readiness/organization-schema.svg" width="720" alt="Describe the organization in JSON-LD: 40.0% of 4,480 home pages read, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
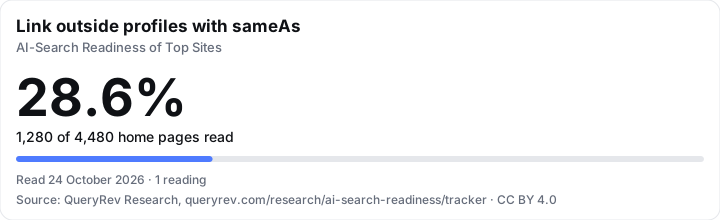
Describe the organization in JSON-LD Edition Read Count Denominator Share October 2026 1,793 of 4,480 home pages read 40.0% Link outside profiles with sameAs 28.6%
1,280 of 4,480 home pages read
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
<a href="https://queryrev.com/research/ai-search-readiness/tracker#organization-same-as"><img src="https://queryrev.com/data/tracker/ai-search-readiness/organization-same-as.svg" width="720" alt="Link outside profiles with sameAs: 28.6% of 4,480 home pages read, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
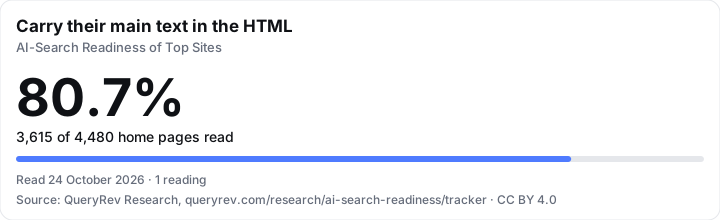
Link outside profiles with sameAs Edition Read Count Denominator Share October 2026 1,280 of 4,480 home pages read 28.6% Carry their main text in the HTML 80.7%
3,615 of 4,480 home pages read
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
<a href="https://queryrev.com/research/ai-search-readiness/tracker#text-in-html"><img src="https://queryrev.com/data/tracker/ai-search-readiness/text-in-html.svg" width="720" alt="Carry their main text in the HTML: 80.7% of 4,480 home pages read, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
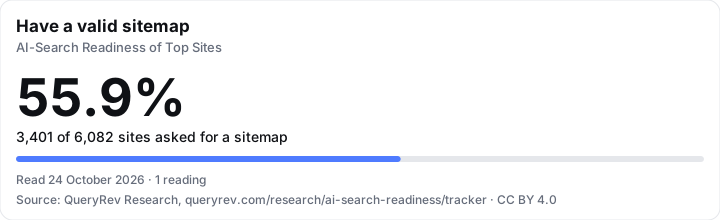
Carry their main text in the HTML Edition Read Count Denominator Share October 2026 3,615 of 4,480 home pages read 80.7% Have a valid sitemap 55.9%
3,401 of 6,082 sites asked for a sitemap
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
<a href="https://queryrev.com/research/ai-search-readiness/tracker#sitemap-valid"><img src="https://queryrev.com/data/tracker/ai-search-readiness/sitemap-valid.svg" width="720" alt="Have a valid sitemap: 55.9% of 6,082 sites asked for a sitemap, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Have a valid sitemap Edition Read Count Denominator Share October 2026 3,401 of 6,082 sites asked for a sitemap 55.9% Publish an llms.txt 13.0%
787 of 6,066 sites asked for an llms.txt
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
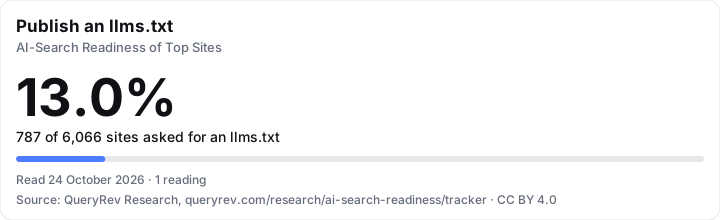
<a href="https://queryrev.com/research/ai-search-readiness/tracker#llms-txt-found"><img src="https://queryrev.com/data/tracker/ai-search-readiness/llms-txt-found.svg" width="720" alt="Publish an llms.txt: 13.0% of 6,066 sites asked for an llms.txt, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Publish an llms.txt Edition Read Count Denominator Share October 2026 787 of 6,066 sites asked for an llms.txt 13.0% Have all five 7.8%
350 of 4,480 home pages read
Read 24 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
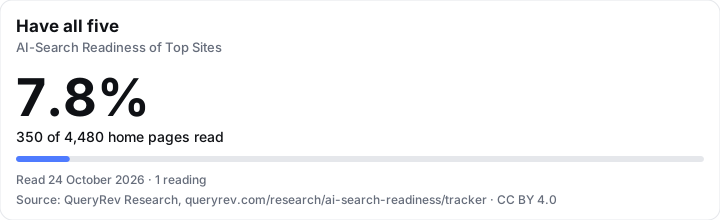
<a href="https://queryrev.com/research/ai-search-readiness/tracker#all-five"><img src="https://queryrev.com/data/tracker/ai-search-readiness/all-five.svg" width="720" alt="Have all five: 7.8% of 4,480 home pages read, read 24 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-search-readiness/tracker">AI-Search Readiness Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Have all five Edition Read Count Denominator Share October 2026 350 of 4,480 home pages read 7.8%
Change log
What each reading found.
The latest reading leads, with the dated files each reading published.
October 2026
Baseline reading: 9,973 domains of Tranco list N26XW read. Each later reading is compared with this one.
Files of this reading
Each new reading adds a point to the tracker and a line to the change log. Follow new readings on Substack
Data
Cite, download and reuse.
The data is free to use under CC BY 4.0: copy, share and adapt it, with a credit and a link to the study. The citation is for the latest reading.
Cite this study
APA
QueryRev Research. (2026). AI-Search Readiness of Top Sites, October 2026 [Data set]. QueryRev AI. https://doi.org/10.5281/zenodo.23632472
BibTeX
@misc{queryrev2026readiness10,
  author = {QueryRev Research},
  title = {{AI-Search Readiness of Top Sites, October 2026}},
  year = {2026},
  month = oct,
  publisher = {QueryRev AI},
  url = {https://queryrev.com/research/ai-search-readiness},
  doi = {10.5281/zenodo.23632472},
  note = {CC BY 4.0}
}The same data, mirrored
The same files under the same licence, on three research data hosts. The DOI is the dataset’s permanent address.
Keep exploring