Research · Tracker
AI Crawler Access Tracker Every reading of the same panel, figure by figure.
How many of the top sites shut AI crawlers out in robots.txt, and how many publish an llms.txt, read again on the same panel. Each figure is a count over the sites read, with the day it was read.
- Readings
- 1
- Latest reading
- 15 October 2026
- Panel
- 9,973 domains, Tranco list N26XW
- Licence
- CC BY 4.0
Updated
Figures
Each figure, reading by reading.
A figure is a count over the sites or pages read in one reading. The scale starts at zero, and every reading names the number it is a share of.
This tracker holds 1 reading. A figure draws a line once it has a second reading.
Block at least one AI crawler by name 14.2%
896 of 6,294 sites read
Read 15 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
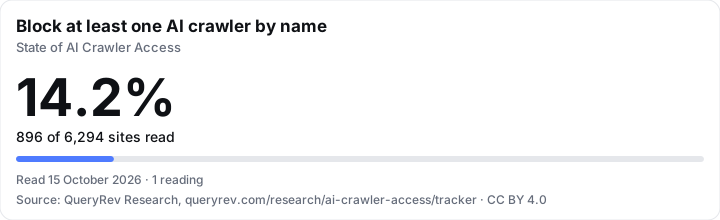
<a href="https://queryrev.com/research/ai-crawler-access/tracker#blocks-any-ai-crawler"><img src="https://queryrev.com/data/tracker/ai-crawler-access/blocks-any-ai-crawler.svg" width="720" alt="Block at least one AI crawler by name: 14.2% of 6,294 sites read, read 15 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-crawler-access/tracker">AI Crawler Access Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Block at least one AI crawler by name Edition Read Count Denominator Share October 2026 896 of 6,294 sites read 14.2% Block GPTBot by name 9.2%
580 of 6,294 sites read
Read 15 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
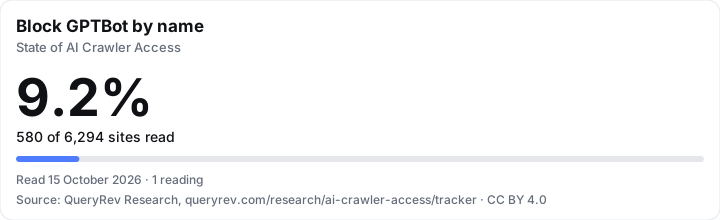
<a href="https://queryrev.com/research/ai-crawler-access/tracker#gptbot-blocked-by-name"><img src="https://queryrev.com/data/tracker/ai-crawler-access/gptbot-blocked-by-name.svg" width="720" alt="Block GPTBot by name: 9.2% of 6,294 sites read, read 15 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-crawler-access/tracker">AI Crawler Access Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Block GPTBot by name Edition Read Count Denominator Share October 2026 580 of 6,294 sites read 9.2% Block every crawler with User-agent: * 3.0%
190 of 6,294 sites read
Read 15 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
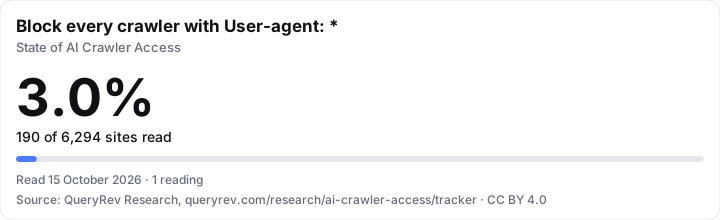
<a href="https://queryrev.com/research/ai-crawler-access/tracker#catch-all-blocks-every-crawler"><img src="https://queryrev.com/data/tracker/ai-crawler-access/catch-all-blocks-every-crawler.svg" width="720" alt="Block every crawler with User-agent: *: 3.0% of 6,294 sites read, read 15 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-crawler-access/tracker">AI Crawler Access Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Block every crawler with User-agent: * Edition Read Count Denominator Share October 2026 190 of 6,294 sites read 3.0% Publish an llms.txt 14.1%
848 of 6,030 sites asked for one
Read 15 October 2026 · 1 reading
See it in the studyEmbed this chart
An image of this figure, linked back to the tracker. It follows each new reading. No script.
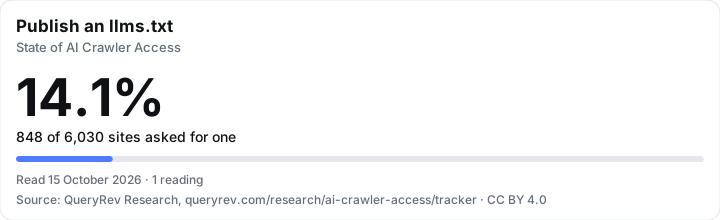
<a href="https://queryrev.com/research/ai-crawler-access/tracker#llms-txt-adoption"><img src="https://queryrev.com/data/tracker/ai-crawler-access/llms-txt-adoption.svg" width="720" alt="Publish an llms.txt: 14.1% of 6,030 sites asked for one, read 15 October 2026. Source: QueryRev Research."></a>
<p>Source: <a href="https://queryrev.com/research/ai-crawler-access/tracker">AI Crawler Access Tracker, QueryRev Research</a> (CC BY 4.0)</p>
Show the numbers as a table
Publish an llms.txt Edition Read Count Denominator Share October 2026 848 of 6,030 sites asked for one 14.1%
Change log
What each reading found.
The latest reading leads, with the dated files each reading published.
October 2026
Baseline reading: 9,973 domains of Tranco list N26XW read. Each later reading is compared with this one.
Files of this reading
Each new reading adds a point to the tracker and a line to the change log. Follow new readings on Substack
Data
Cite, download and reuse.
The data is free to use under CC BY 4.0: copy, share and adapt it, with a credit and a link to the study. The citation is for the latest reading.
Cite this study
APA
QueryRev Research. (2026). State of AI Crawler Access, October 2026 [Data set]. QueryRev AI. https://doi.org/10.5281/zenodo.23424275
BibTeX
@misc{queryrev2026crawler10,
  author = {QueryRev Research},
  title = {{State of AI Crawler Access, October 2026}},
  year = {2026},
  month = oct,
  publisher = {QueryRev AI},
  url = {https://queryrev.com/research/ai-crawler-access},
  doi = {10.5281/zenodo.23424275},
  note = {CC BY 4.0}
}The same data, mirrored
The same files under the same licence, on three research data hosts. The DOI is the dataset’s permanent address.
Keep exploring